Yushu Wu

Software Engineer @ Google

My research focuses on video generation and world models. I work on diffusion transformer architectures, video latent spaces, and long-horizon memory for real-time, interactive video generation, and on world action models that use visual foresight to guide action.

I am currently a Software Engineer at Google, where I worked on generative media and now work on multimodal Gemma models. Before that, I received my Ph.D. in Computer Engineering from Northeastern University, advised by Prof. Yanzhi Wang, and interned at Snap and Epic Games on video generation and world models.

I am always eager to explore new problems, which has taken me from ML systems to video generation and world models.

Research

  • Diffusion Models & Video Generation
    Diffusion transformer architectures, video autoencoders, few-step sampling, and diffusion-based dataset distillation.
    S2DiT (CVPR'26) · SnapGen-V+ (Preprint) · D3HR (ICML'25) · SnapGen-V (CVPR'25) · H3AE (Preprint) · Streamlined Inference (NeurIPS'24) · SF-V (NeurIPS'24)
  • World Models & Long Video Generation
    Long-horizon memory for autoregressive video generation and visual action reasoning for world action models.
    Event-Aligned WAM (Preprint) · OmniMem (NeurIPS'26)
  • State Space Models
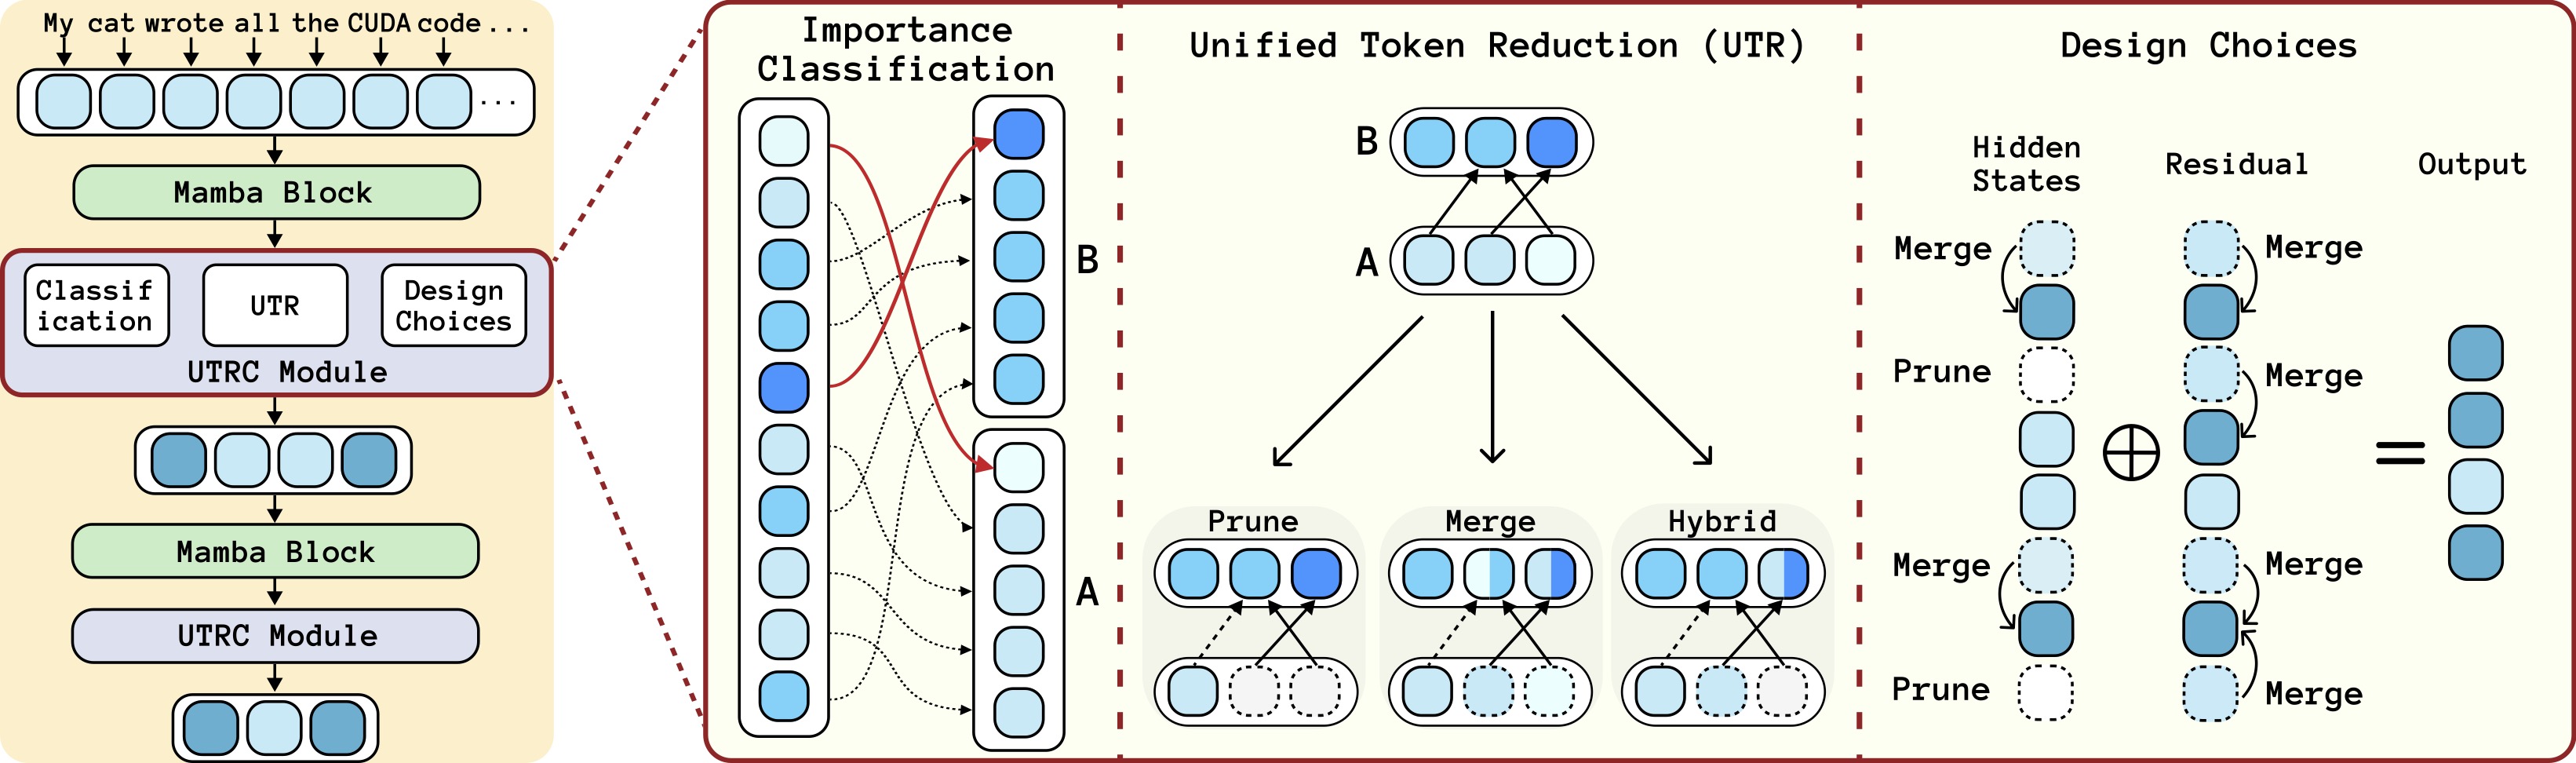
    Analyzing and reducing token redundancy in vision and language state space models.
    ToP-ViM (NeurIPS'24) · ToR-SSM (EMNLP'24)
  • ML Systems & Hardware–Software Co-Design
    CPU–GPU co-optimization, runtime thermal and latency management, and compiler-aware neural architecture search for DNN inference.
    LOTUS (DAC'24) · DACO (DATE'24) · MOC (ICCAD'23) · Compiler-Aware NAS (ECCV'22)

Recent News

Preprints

Event-Aligned Visual Action Reasoning for World Action Models Preprint
Xiaomeng Yang, Yushu Wu†, Yi Gao, Yuhao Lei, Xuan Zhang, Pu Zhao, Yanzhi Wang
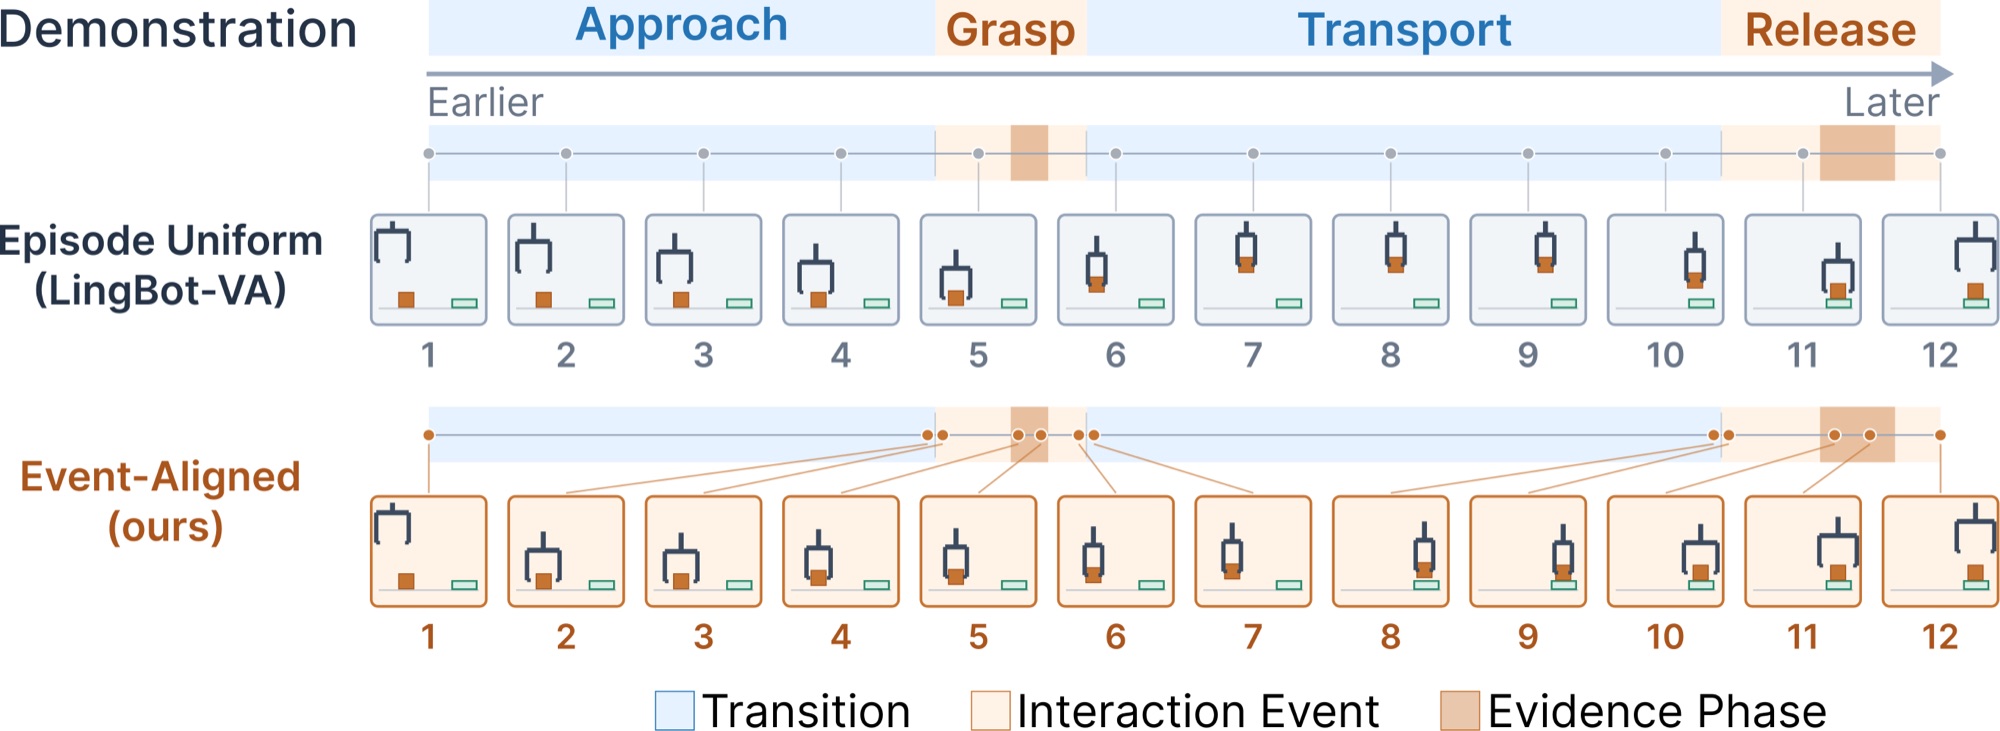
We organize the visual foresight of World Action Models around interaction events instead of fixed temporal intervals, spending fine-grained visual reasoning on task-critical interactions and coarser progression on connecting transitions. An execution validity head further removes redundant actions during chunked inference, improving DOMINO success rate by 10.26 points over the baseline with competitive performance on RoboTwin 2.0.
Taming Diffusion Transformer for Efficient Mobile Video Generation in Seconds Preprint
Yushu Wu*, Yanyu Li*, Anil Kag, Ivan Skorokhodov, Willi Menapace, Ke Ma, Arpit Sahni, Ju Hu, Aliaksandr Siarohin, Dhritiman Sagar, Yanzhi Wang, Sergey Tulyakov
We investigate architectural and training adaptations that enable diffusion transformers to operate efficiently on mobile platforms. Our study analyzes the trade-offs between denoising step reduction, model scaling, and visual fidelity, providing principled strategies for real-time video generation on edge devices.
H3AE: High Compression, High Speed, and High Quality AutoEncoder for Video Diffusion Models Preprint
Yushu Wu*, Yanyu Li*, Ivan Skorokhodov, Anil Kag, Willi Menapace, Sharath Girish, Aliaksandr Siarohin, Yanzhi Wang, Sergey Tulyakov
[paper]
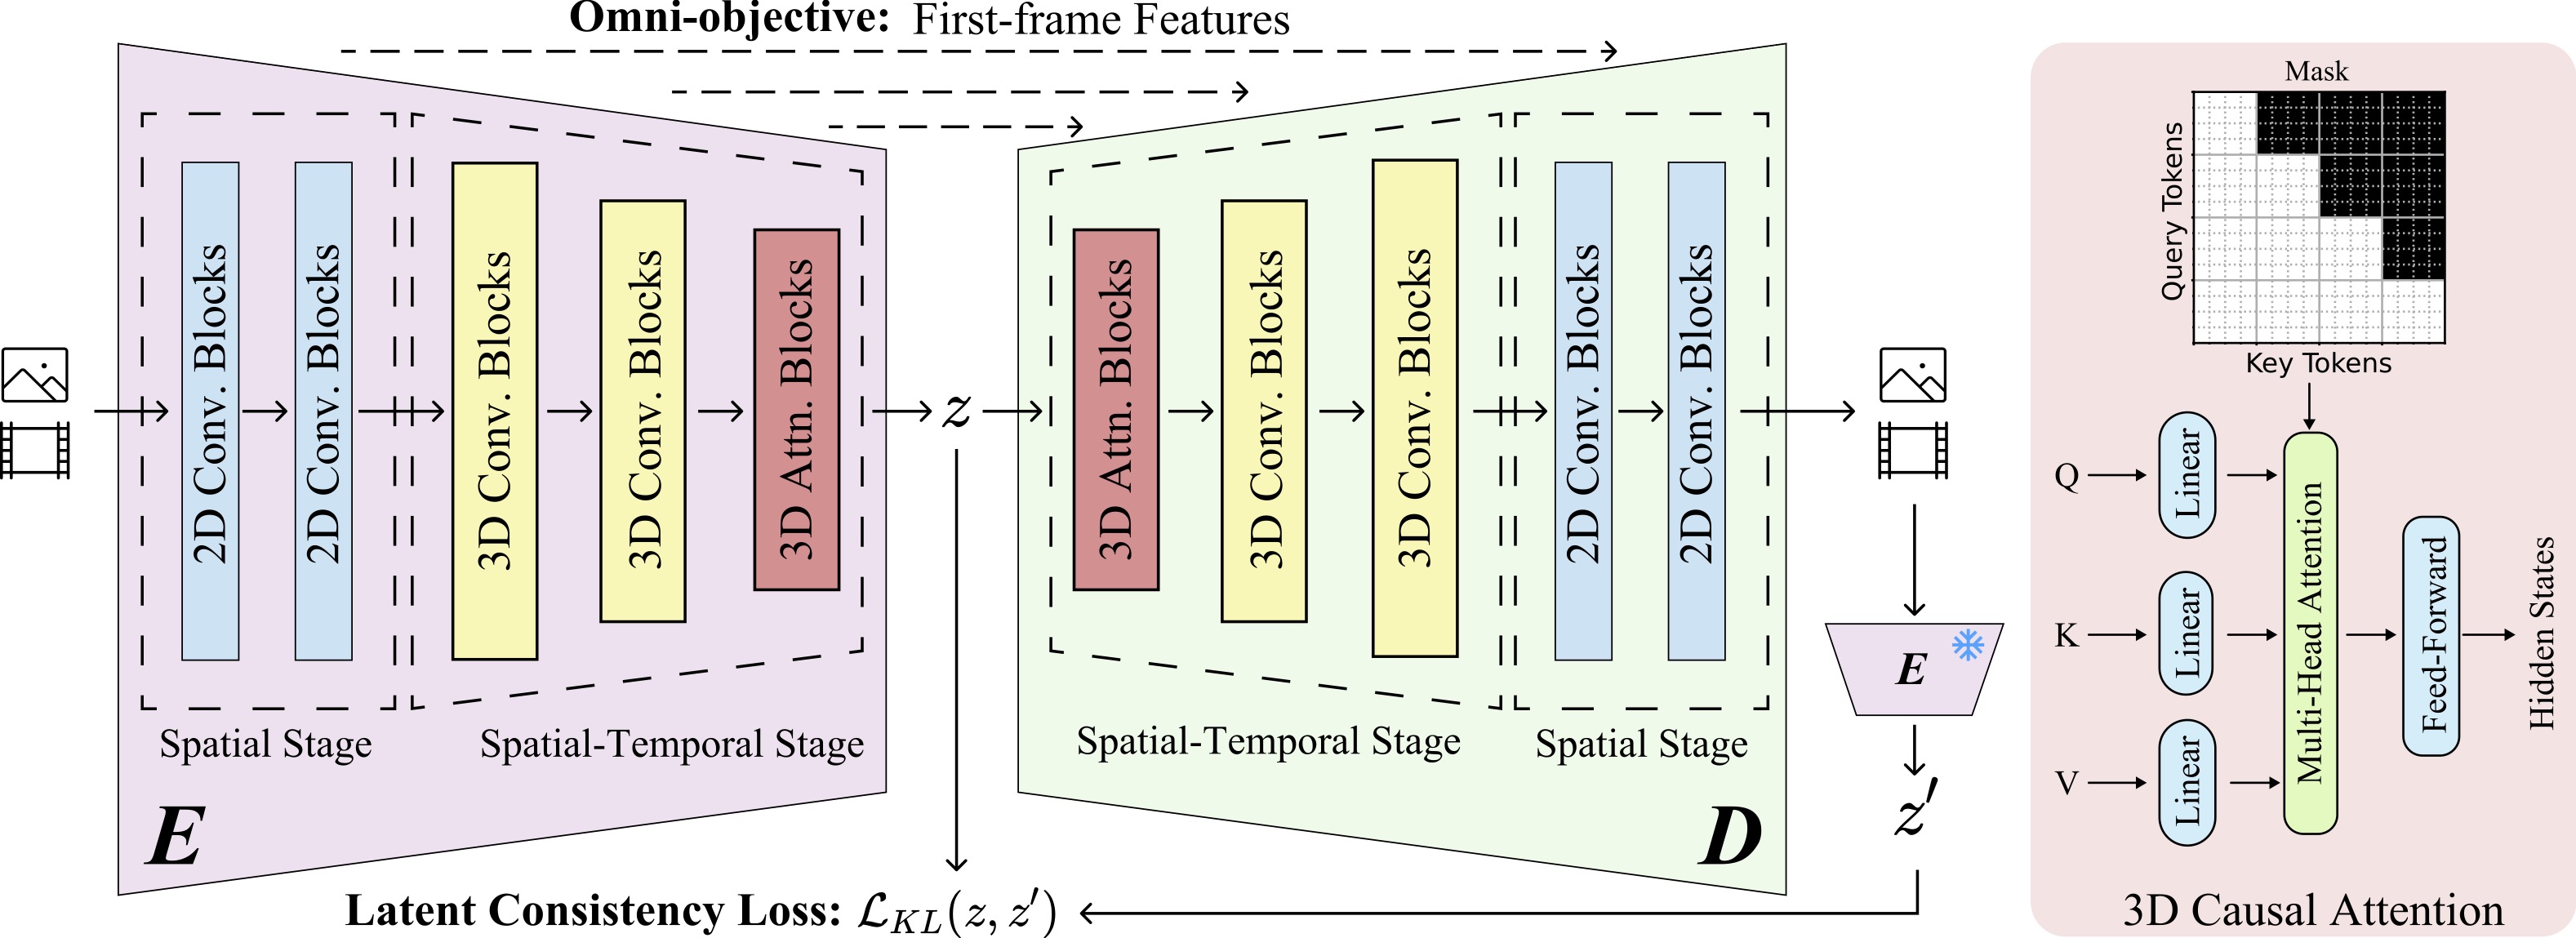
We introduce a high-compression autoencoder tailored for video diffusion models, aiming to reduce latent dimensionality while preserving perceptual fidelity. H3AE systematically balances reconstruction quality, bitrate, and downstream generative performance, enabling scalable video diffusion under limited memory budgets.

Selected Publications

See all publications or Google Scholar. * means equal contribution. † means project lead.

OmniMem: Scalable and Adaptive Memory Retrieval for Long Video Generation NeurIPS
Yushu Wu*, Lin Zhao*, Yifan Gong, Yanzhi Wang, Pu Zhao
Conference on Neural Information Processing Systems (NeurIPS), 2026.
[paper][project][code]
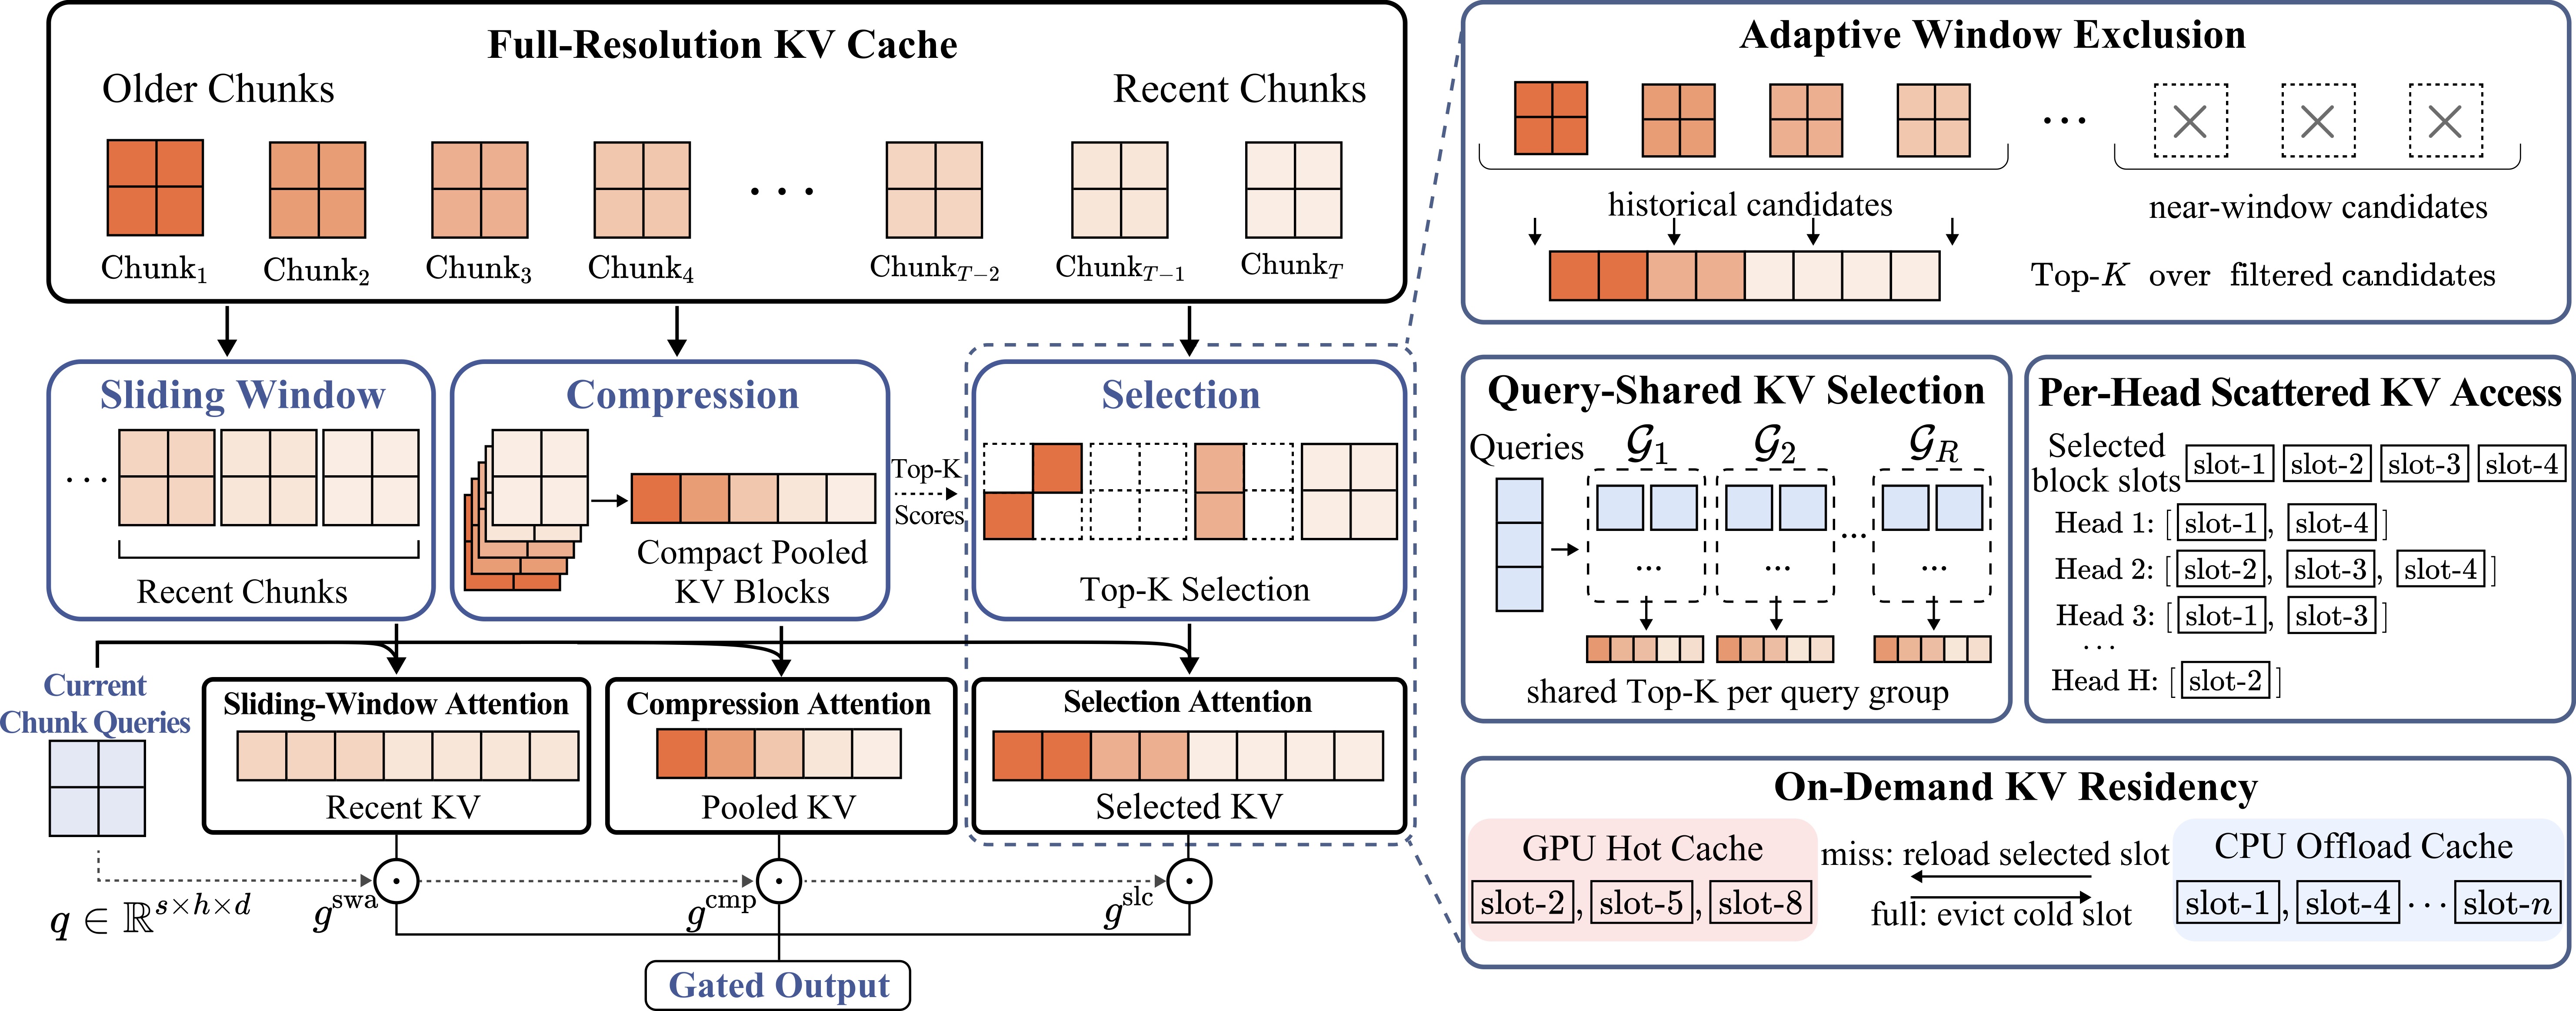
OmniMem does explicit sparse KV retrieval over the full history for autoregressive long-video generation, keeping the query-relevant details that are lost when the KV cache is truncated or compressed, and improves Dynamic Degree by 52.3% at comparable memory cost.
S2DiT: Sandwich Diffusion Transformer for Mobile Streaming Video Generation CVPR
Yushu Wu*, Lin Zhao*, Aleksei Lebedev, Dishani Lahiri, Meng Dong, Arpit Sahni, Michael Vasilkovsky, Hao Chen, Ju Hu, Aliaksandr Siarohin, Sergey Tulyakov, Yanzhi Wang, Anil Kag, Yanyu Li
Conference on Computer Vision and Pattern Recognition (CVPR), 2026.
[paper]
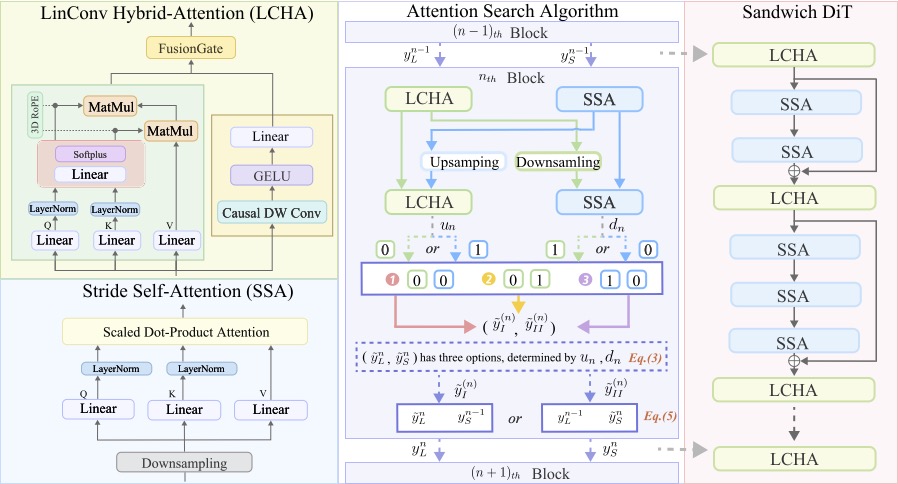
We propose an interleaved multi-resolution diffusion transformer architecture that departs from conventional hourglass designs. By distributing high- and low-resolution blocks in a mixed topology, S2DiT improves memory efficiency and temporal coherence for streaming video generation under constrained compute budgets.
Taming Diffusion for Dataset Distillation with High Representativeness ICML
Lin Zhao, Yushu Wu, Xinru Jiang, Jianyang Gu, Yanzhi Wang, Xiaolin Xu, Pu Zhao, Xue Lin
The International Conference on Machine Learning (ICML), 2025.
[paper][code]
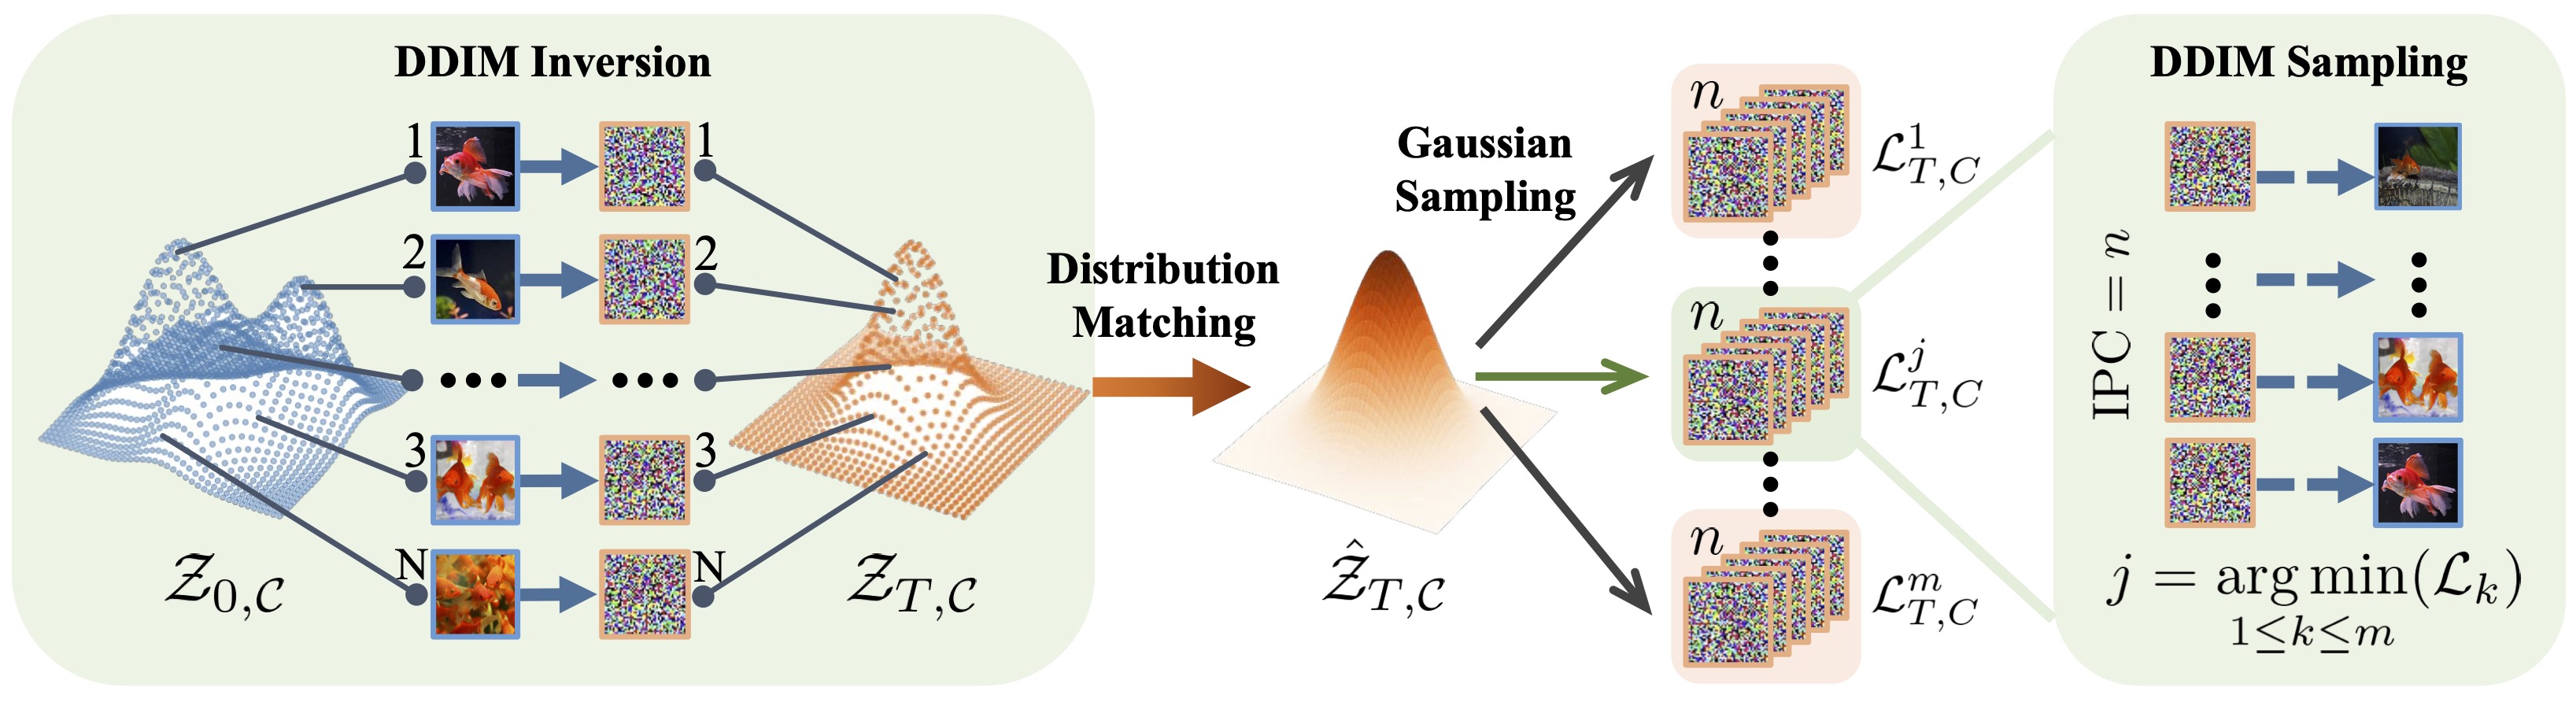
Proposed a novel diffusion-based dataset distillation framework, utilizing DDIM inversion and latent distribution matching to synthesize compact datasets, maintaining high representativeness for efficient downstream training.
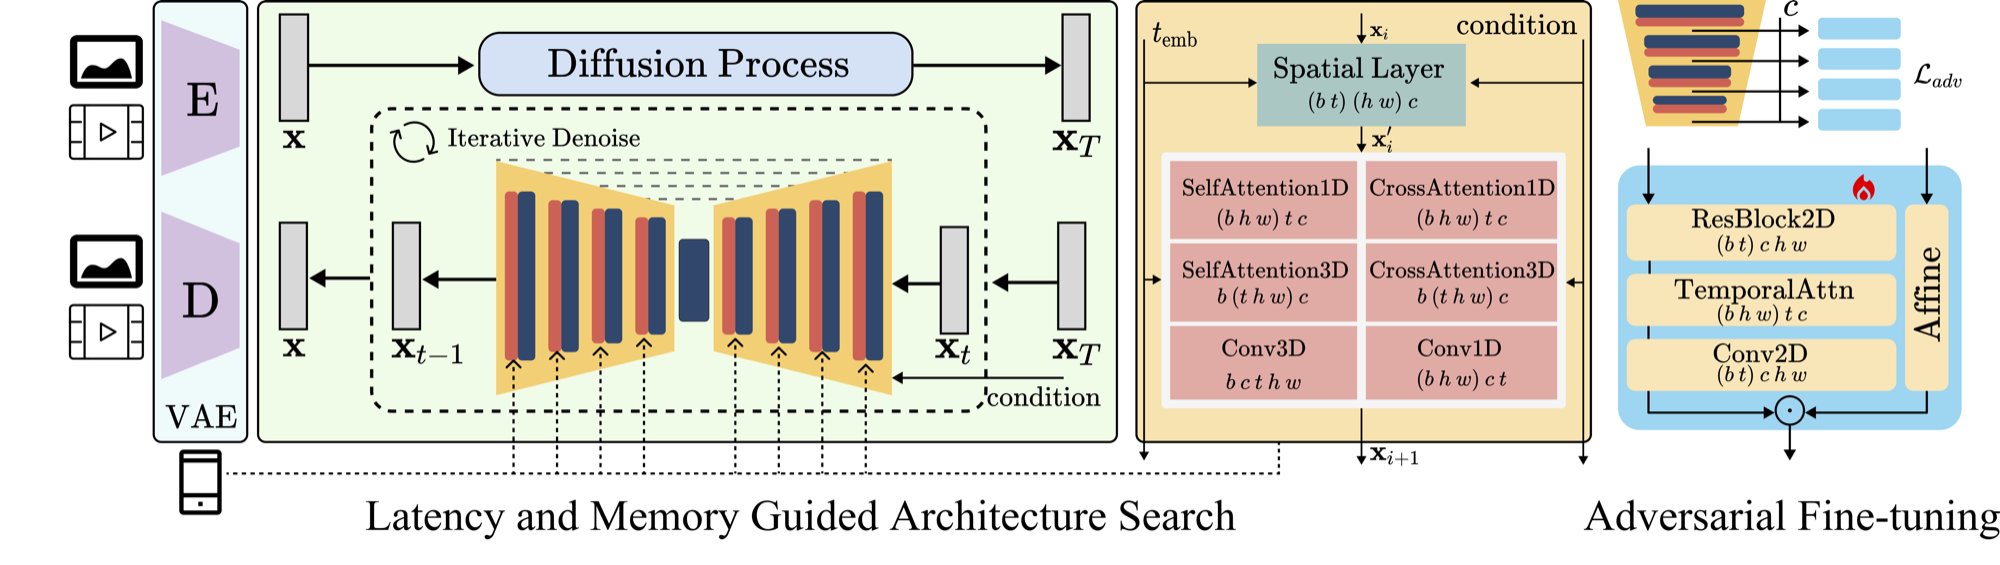
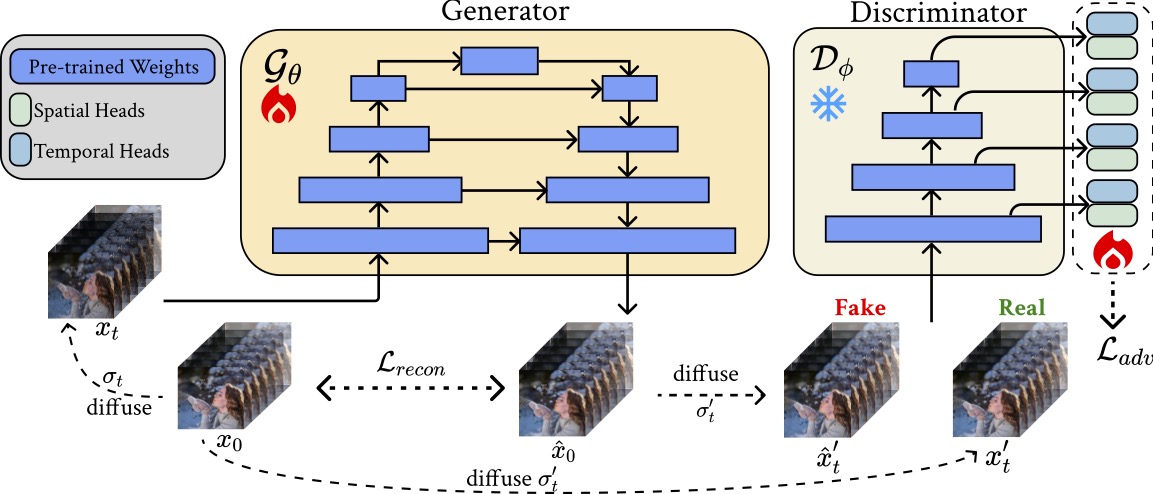
SnapGen-V: Generating a Five-Second Video within Five Seconds on a Mobile Device CVPR
Yushu Wu*, Zhixing Zhang*, Yanyu Li*, Yanwu Xu, Anil Kag, Yang Sui, Huseyin Coskun, Ke Ma, Aleksei Lebedev, Ju Hu, Dimitris Metaxas, Yanzhi Wang, Sergey Tulyakov, Jian Ren
Conference on Computer Vision and Pattern Recognition (CVPR), 2025.
[paper][project]
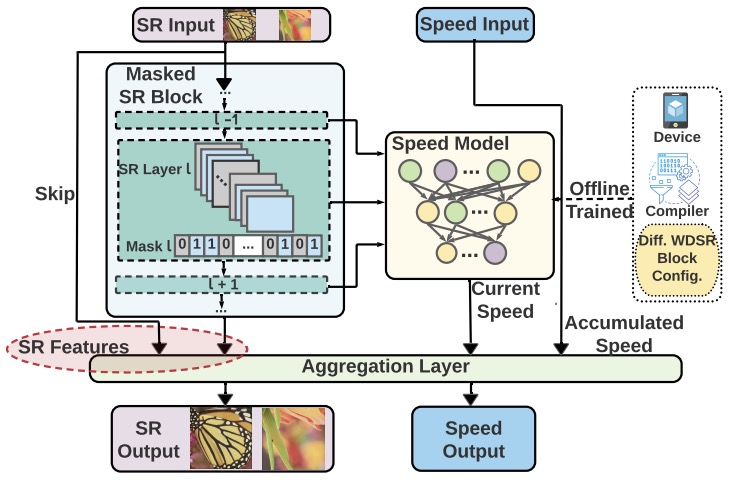
SnapGen-V presents a full-stack acceleration framework for large-scale video diffusion models on edge devices. By combining adversarial step distillation, mobile-aware architecture redesign, and inference scheduling optimization, we demonstrate real-time video generation on mobile hardware.
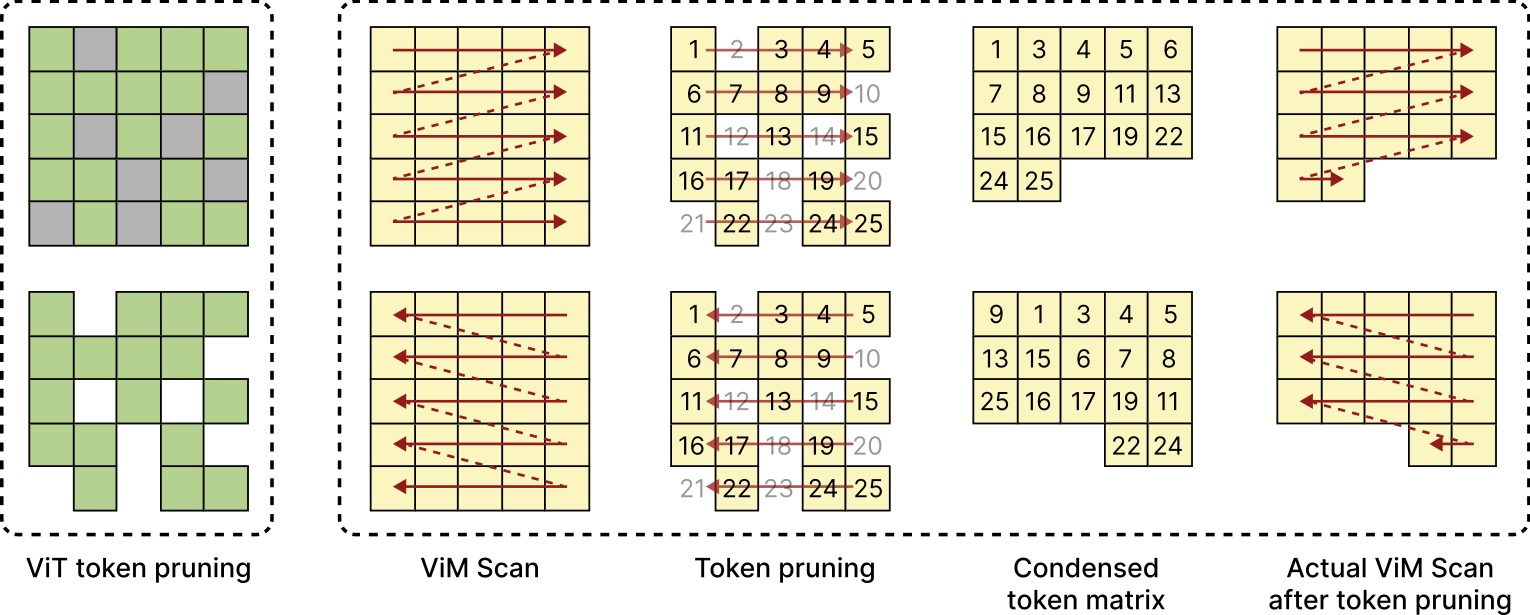
Exploring token pruning in vision state space models NeurIPS
Zheng Zhan*, Zhenglun Kong*, Yifan Gong*, Yushu Wu, Zichong Meng, Hangyu Zheng, Xuan Shen, Stratis Ioannidis, Wei Niu, Pu Zhao, Yanzhi Wang
Conference on Neural Information Processing Systems (NeurIPS), 2024.
[paper][code]
We study structured token pruning strategies for state space models, analyzing their impact on sequence modeling efficiency and representation fidelity. Our findings reveal principled sparsification patterns that preserve downstream performance under reduced computational budgets.
SF-V: Single Forward Video Generation Model NeurIPS
Zhixing Zhang, Yanyu Li, Yushu Wu, Yanwu Xu, Anil Kag, Ivan Skorokhodov, Willi Menapace, Aliaksandr Siarohin, Junli Cao, Dimitris Metaxas, Sergey Tulyakov, Jian Ren
Conference on Neural Information Processing Systems (NeurIPS), 2024.
[paper][project]
SF-V explores single-forward video generation to reduce iterative denoising overhead in diffusion models. By reformulating temporal generation dynamics, the method improves efficiency while maintaining competitive visual fidelity.
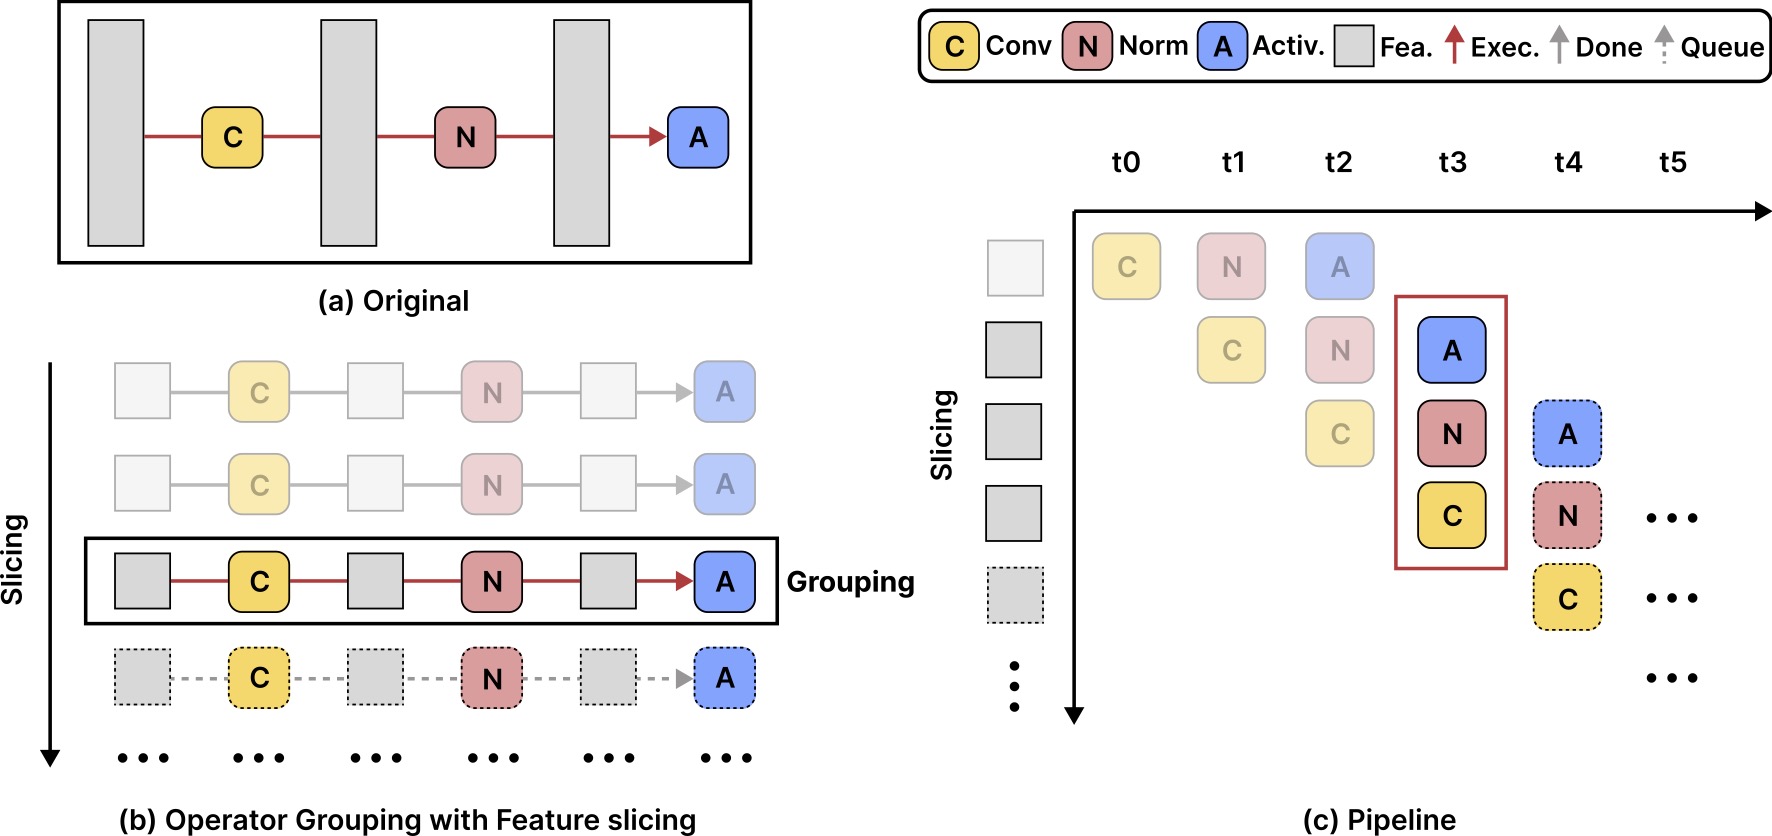
Fast and Memory-Efficient Video Diffusion Using Streamlined Inference NeurIPS
Yushu Wu*, Zheng Zhan*, Yifan Gong, Zichong Meng, Zhenglun Kong, Changdi Yang, Geng Yuan, Pu Zhao, Wei Niu, Yanzhi Wang
Conference on Neural Information Processing Systems (NeurIPS), 2024.
[paper][code]
We propose a streamlined inference pipeline for video diffusion models, addressing the high memory footprint and computational cost of temporal attention mechanisms. Our approach integrates memory-aware attention restructuring and dynamic scheduling to enable efficient single-GPU training and inference.
Rethinking Token Reduction for State Space Models EMNLP
Yushu Wu*, Zheng Zhan*, Zhenglun Kong*, Changdi Yang, Yifan Gong, Xuan Shen, Xue Lin, Pu Zhao, Yanzhi Wang
Conference on Empirical Methods in Natural Language Processing (EMNLP), 2024.
[paper][code]
ToR-SSM investigates token reduction mechanisms in sequence models for language and vision tasks. We characterize the interaction between sparsification, representation stability, and generalization, offering insights into scalable sequence modeling.
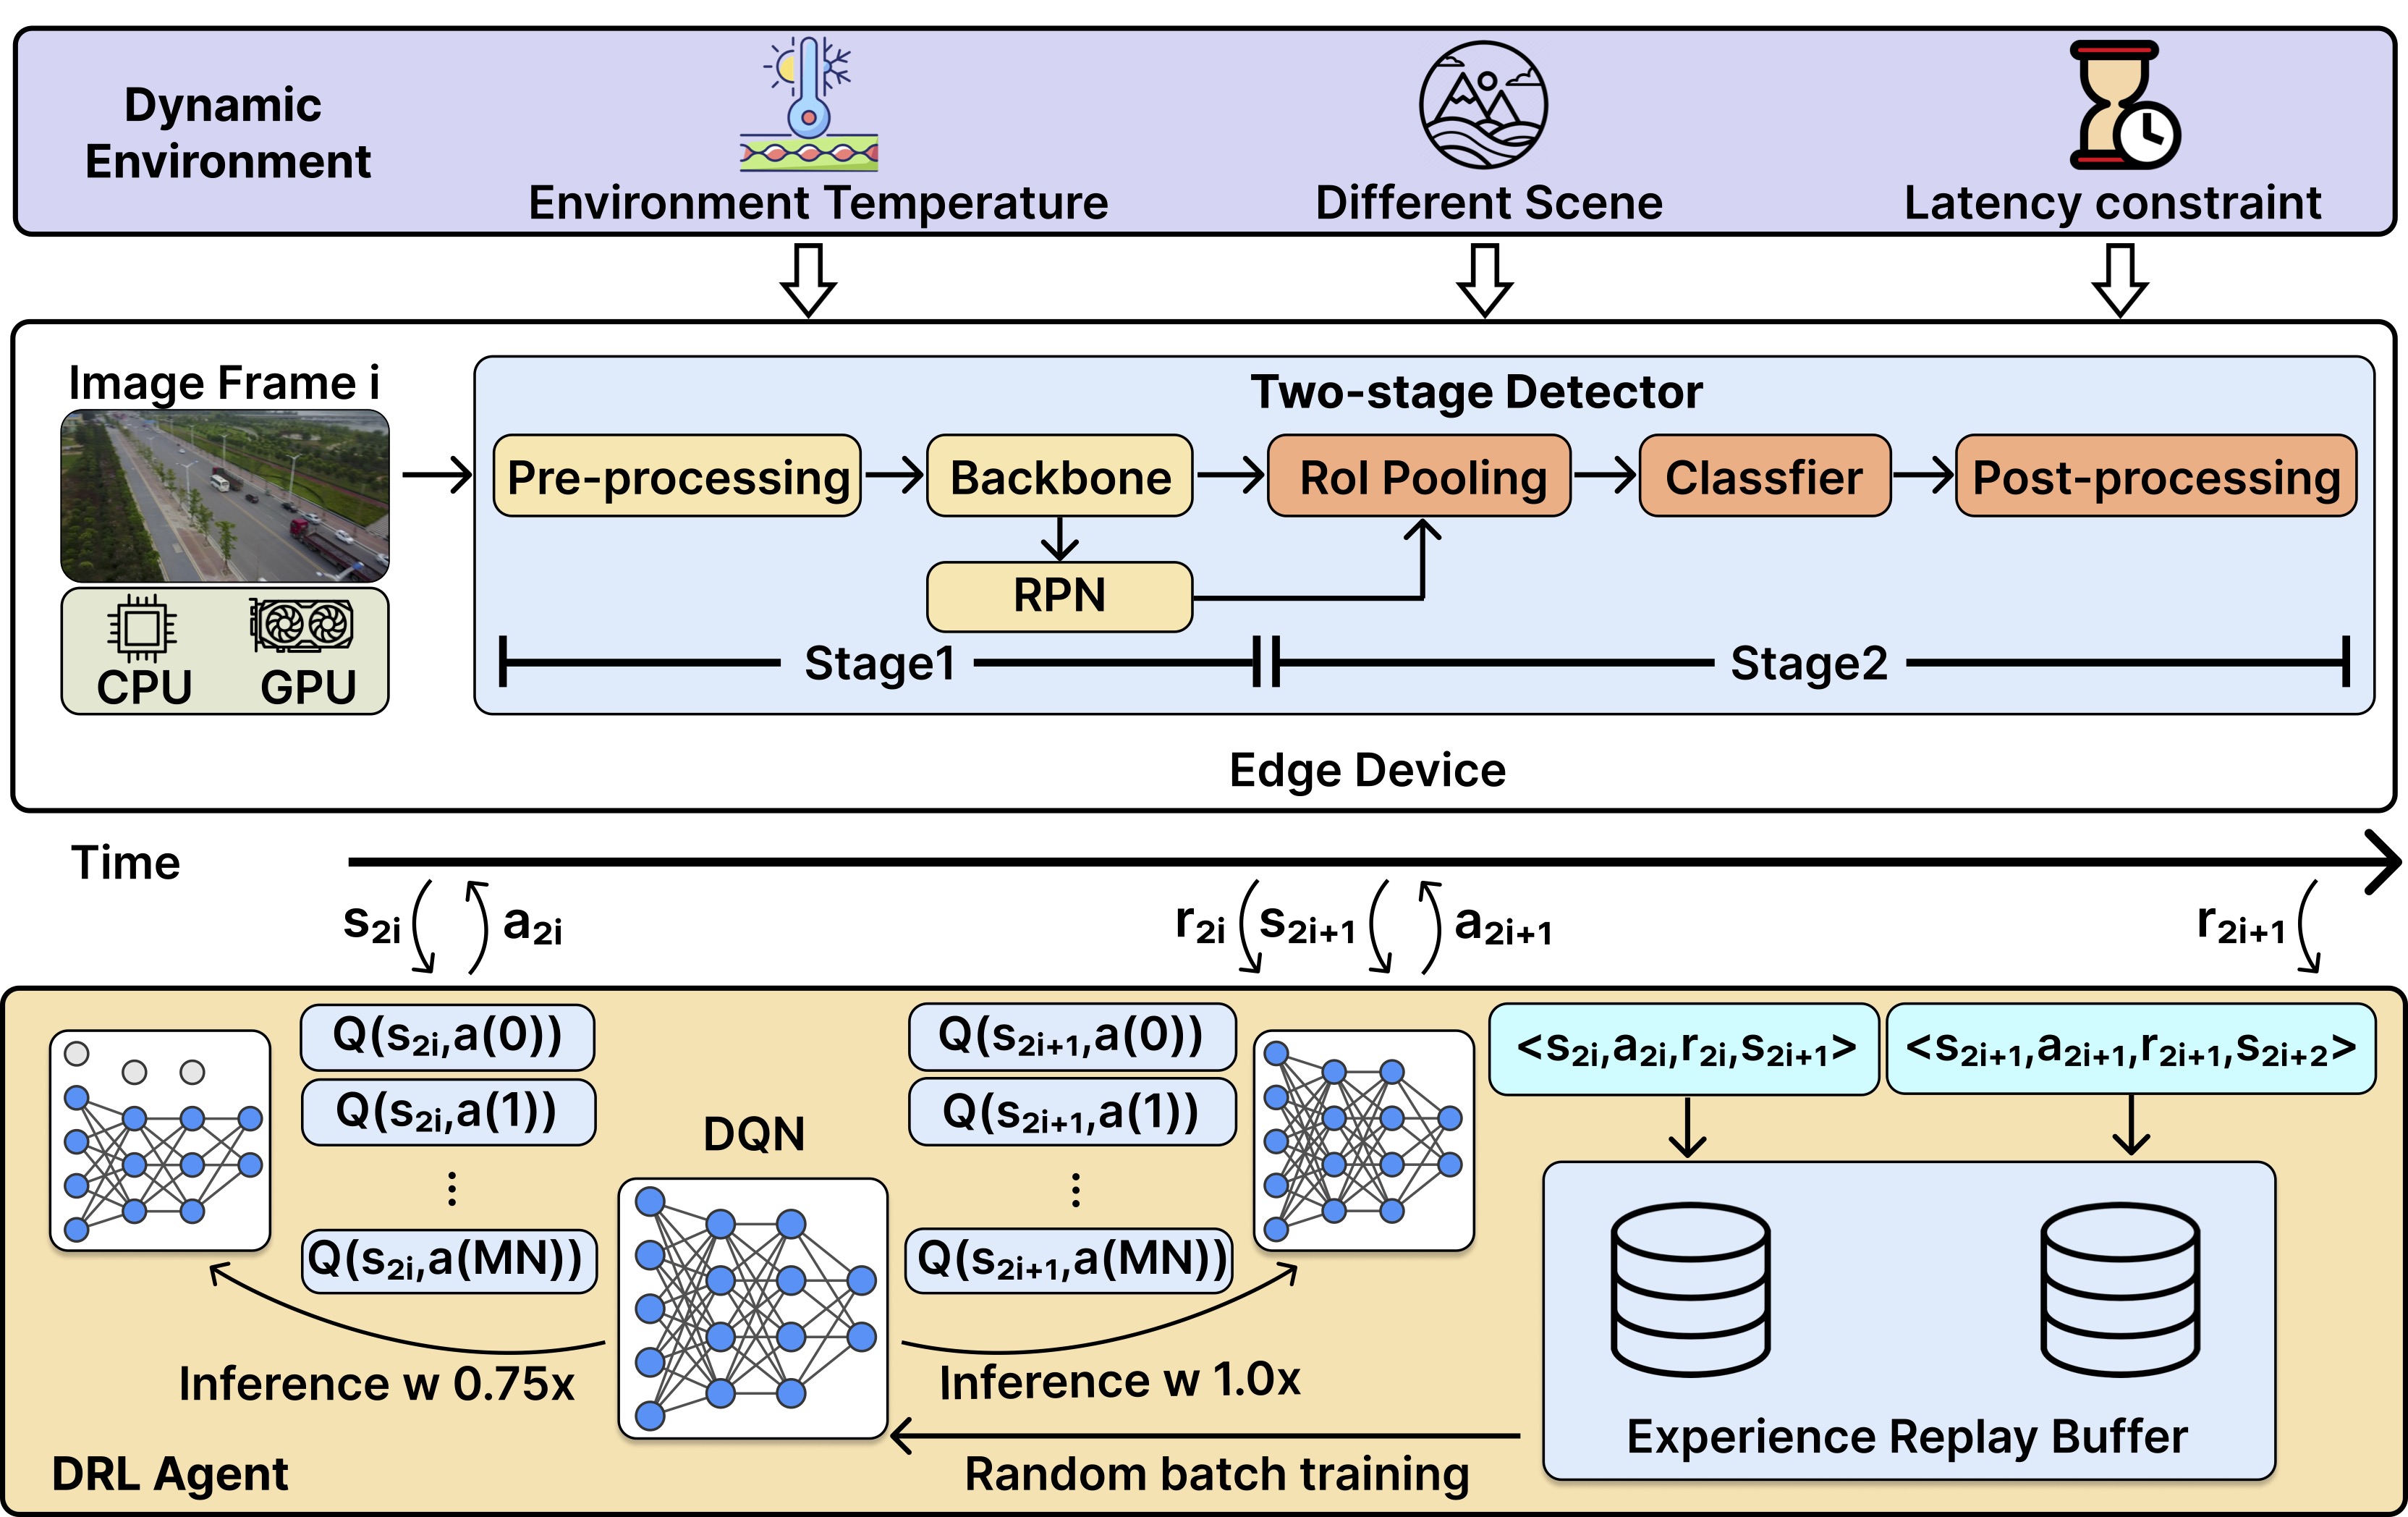
Lotus: learning-based online thermal and latency variation management for two-stage detectors on edge devices DAC
Yushu Wu*, Yifan Gong*, Zheng Zhan*, Pu Zhao, Liangkai Liu, Chao Wu, Xulong Tang, Yanzhi Wang
Proceedings of the 61st ACM/IEEE Design Automation Conference (DAC), 2024.
[paper][code]
LOTUS introduces a learning-based framework for online thermal and latency management in edge AI systems. By jointly modeling dynamic voltage-frequency scaling and workload variation, the method achieves energy-efficient deployment under runtime constraints.
DACO: Pursuing Ultra-low Power Consumption via DNN-Adaptive CPU-GPU CO-optimization on Mobile Devices DATE
Yushu Wu, Chao Wu, Geng Yuan, Yanyu Li, Weichao Guo, Jing Rao, Xipeng Shen, Bin Ren, Yanzhi Wang
Design, Automation and Test in Europe Conference and Exhibition (DATE), 2024.
[paper]
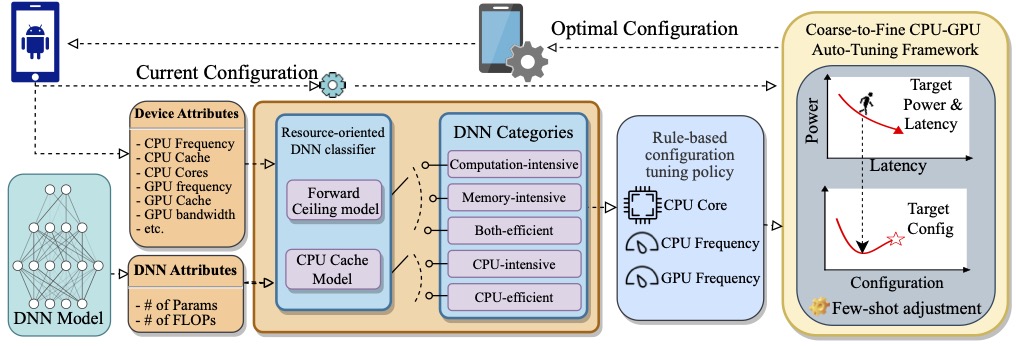
DACO presents a compression-DVFS co-design framework that adaptively adjusts model sparsity and hardware frequency to minimize energy consumption while preserving runtime performance.
“It is Okay to be Uncommon”: Quantizing Sound Event Detection Networks on Hardware Accelerators with Uncommon Sub-Byte Support ICASSP
Yushu Wu, Xiao Quan, Mohammad Rasool Izadi, Chuan-Che Jeff Huang
International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2024.
[paper]
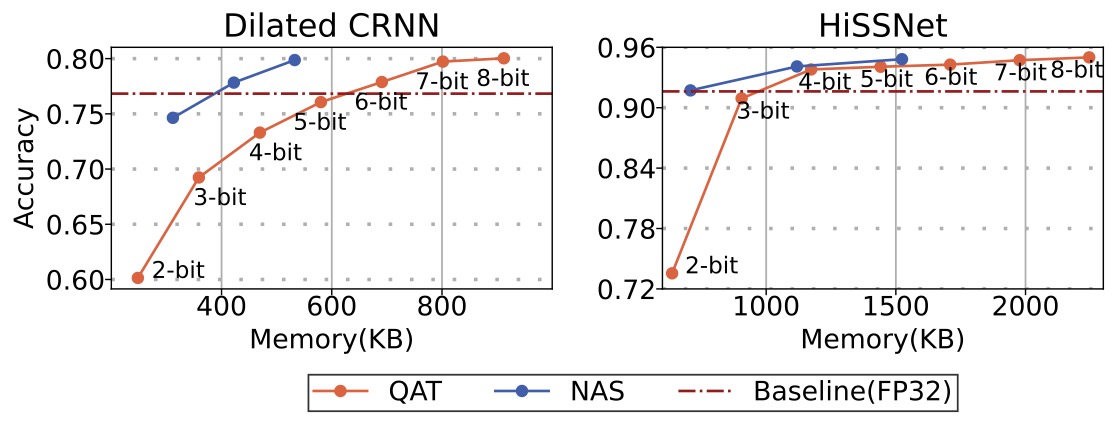
We investigate sub-byte quantization strategies for sound event detection on hardware accelerators that support uncommon bit-width representations. By relaxing conventional uniform quantization assumptions, we demonstrate improved accuracy-efficiency trade-offs under constrained memory and compute budgets.
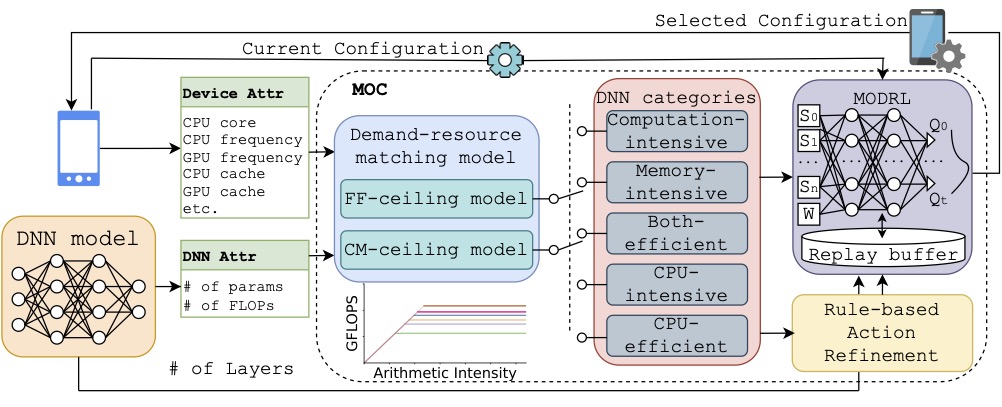
MOC: Multi-Objective Mobile CPU-GPU Co-optimization for Power-efficient DNN Inference ICCAD
Yushu Wu*, Yifan Gong*, Zheng Zhan, Geng Yuan, Yanyu Li, Qi Wang, Chao Wu, Yanzhi Wang
International Conference on Computer Aided Design (ICCAD), 2023.
[paper]
MOC formulates CPU-GPU co-optimization for DNN inference as a multi-objective optimization problem, balancing power consumption, latency, and thermal constraints on mobile platforms.
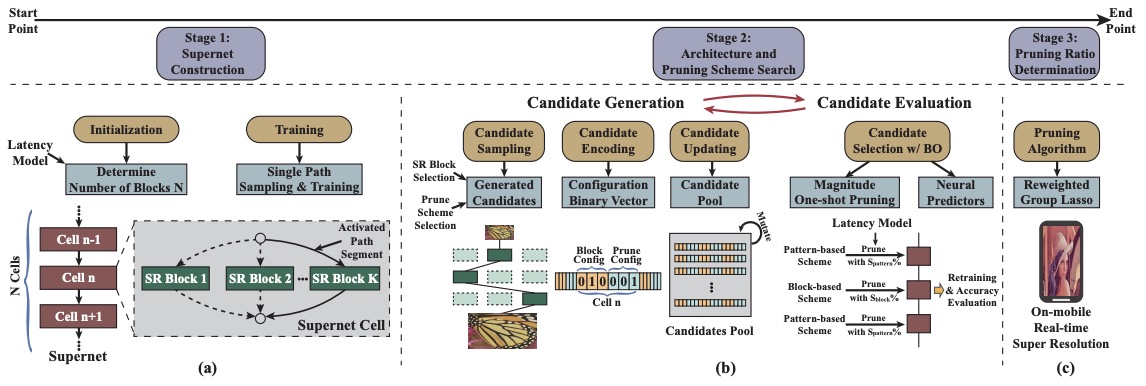
Compiler-Aware Neural Architecture Search for On-Mobile Real-time Super-Resolution ECCV
Yushu Wu*, Yifan Gong*, Pu Zhao, Yanyu Li, Zheng Zhan, Wei Niu, Hao Tang, Minghai Qin, Bin Ren, Yanzhi Wang
European Conference on Computer Vision (ECCV), 2022.
[paper][code]
We propose a compiler-aware neural architecture search framework for real-time super-resolution on mobile devices. By incorporating hardware- and compiler-level constraints directly into the search objective, the resulting architectures achieve improved latency-quality trade-offs and reliable deployment across mobile runtimes.
Achieving on-Mobile Real-Time Super-Resolution with Neural Architecture and Pruning Search ICCV
Zheng Zhan*, Yifan Gong*, Pu Zhao*, Geng Yuan, Wei Niu, Yushu Wu, Tianyun Zhang, Malith Jayaweera, David Kaeli, Bin Ren, Xue Lin, Yanzhi Wang
International Conference on Computer Vision (ICCV), 2021.
[paper]
We present a neural architecture and pruning search framework for achieving real-time super-resolution on mobile devices. By jointly optimizing network topology and structured sparsity under hardware constraints, the resulting models deliver favorable latency-quality trade-offs and reliable on-device performance.

Experience

Software Engineer, AI Edge, Google

Jul 2026 - Present, Sunnyvale, CA

Worked on generative media; now on multimodal Gemma models

Research Intern, Epic Games, Inc.

Jan 2026 - June 2026, Boston, MA (Remote)

Worked on World Model

Research Intern, Creative Vision, Snap Inc.

May 2024 - Dec 2025, Santa Monica, CA

Worked on text-to-video diffusion models

Research Intern, Bose Corporation

Jan 2023 - August 2023, Framingham, MA

Worked on audio model quantization for NPU deployment

Education

Ph.D. in Computer Engineering, Northeastern University

Sep 2018 - Jun 2026, Boston, MA

Advised by Prof. Yanzhi Wang. M.S. in Computer and Electrical Engineering awarded en route (2024).

B.Eng. in Electrical Engineering, Shandong University

Sep 2014 - Jun 2018, Jinan, China